AI BOX
Edge AI computing terminal
Armv9 12-core CPU and 45 TOPS NPU, with an optional 200 / 400 / 800 TOPS GPU.
10B-parameter-class large models and 128 video channels run on the device.
45TOPS
NPU compute
INT8, standard on all versions
400TOPS
GPU compute
INT8, Max
64GB
GPU VRAM
Max
128ch
1080p@30fps decoding
Plus 16-channel encoding
Versions
Four versions
Same chassis and mainboard with identical CPU, NPU, memory and storage, differentiated by GPU compute and VRAM. Standard has no GPU.
NPU 45 TOPS (all versions) GPU (INT8)
| Standard | Pro | Max | Pro Max | |
|---|---|---|---|---|
| Compute units | CPU + NPU | CPU + NPU + GPU | CPU + NPU + GPU | CPU + NPU + GPU |
| NPU (INT8) | 45 TOPS | 45 TOPS | 45 TOPS | 45 TOPS |
| GPU (INT8) | — | 200 TOPS | 400 TOPS | 800 TOPS |
| VRAM | — | 32 GB | 64 GB | 128 GB |
| CPU | Armv9 12-core | Armv9 12-core | Armv9 12-core | Armv9 12-core |
| Memory | 16 GB LPDDR5x, up to 64 GB | 16 GB LPDDR5x, up to 64 GB | 16 GB LPDDR5x, up to 64 GB | 16 GB LPDDR5x, up to 64 GB |
| Positioning | Comparable to NVIDIA Jetson Orin series | Local inference of mid-size models | Local inference of 10B-parameter-class models | Larger models and concurrent multi-task workloads |
Max figures are from Product spec sheet V1.0; power consumption, dimensions and the local model list are Max values. For other versions, refer to the corresponding spec sheet.
Heterogeneous compute
Division of work across CPU, NPU and GPU
Control and scheduling run on the CPU, always-on vision and mid-size models on the NPU, and large models and parallel computing on the GPU. The three compute units work together in one device, so robots can be deployed with an integrated "large and small brain" architecture.
CPU
Armv9 12-core
A720 × 8 + A520 × 4, system > 300 KDMIPS
- Task scheduling and business logic
- SLAM, path planning, motion control
- ROS nodes and device drivers
NPU
45 TOPS
INT8, standard on all versions
- Vision detection and recognition models
- Qwen3-30B-A3B, Qwen3-VL-30B-A3B
- Low-power always-on inference
GPU
400 TOPS
INT8, 64 GB VRAM (Max)
- Qwen3.5-122B-A10B large model
- CUDA-compatible parallel computing
- Radar signal and pixel-level image processing
Local large models
A 122B model,
on the device
The Max GPU runs Qwen3.5-122B-A10B; the NPU simultaneously runs 30B-class MoE language models and vision language models. Models, data and inference all stay local.
Adapted models listed in the Max spec sheet.
Video processing
128-channel video decoding
Integrated video codec unit: 128-channel 1080p@30fps decoding and 16-channel 1080p@30fps encoding, supporting H.264, H.265 and AVS2. Decoded video streams go directly to the NPU / GPU for analysis.
16-ch encoding 128-ch decoding
Software and applications
Software ecosystem and applications
- GPU ecosystem
- CUDA-compatible; existing CUDA applications can be migrated
- Deep learning frameworks
- PyTorch, TensorFlow, ONNX Runtime, TensorRT
- Multimedia frameworks
- FFmpeg, GStreamer
- Robotics
- All ROS versions supported
- Operating system
- Debian 12 / Ubuntu 26.04
Robot navigation and motion control
Runs SLAM, path planning and obstacle avoidance simultaneously, working with the low-level motion control unit; the CPU handles control while the NPU / GPU run perception and decision models.
Local large model inference
Edge AI assistants, medical imaging, industrial quality inspection and similar uses, running LLMs and VLMs on the device so data stays on site.
Multi-channel video analytics
128-channel 1080p decoding with object detection, behavior recognition and anomaly detection, reducing video upload bandwidth.
Parallel computing
Data-intensive tasks such as parallel radar signal processing, large-scale pixel-level image processing and bulk data encryption.
Application
Edge–cloud hybrid for enterprise agents
AI BOX serves as the model entry point for enterprise agents. Class A deterministic tasks run as local programs, class B routine semantic tasks go to the local large model, and class C complex multi-step tasks and class D high-risk tasks call cloud models under the egress policy.
- Unified access
- OpenAI-compatible API; cloud API keys are stored encrypted on the device and never issued to employees or agents
- Result checks
- Local output is checked for format, fields, value ranges and traceability to the source text; on failure, timeout or a complexity match, the request escalates to the cloud and the reason is logged
- Egress policy
- Set per data sensitivity level: no egress, egress after masking, or specified cloud vendors only
- Audit and budget
- Each call logs user, category, actual model, escalation reason, tokens and duration; daily / monthly budgets per user and department
Hardware
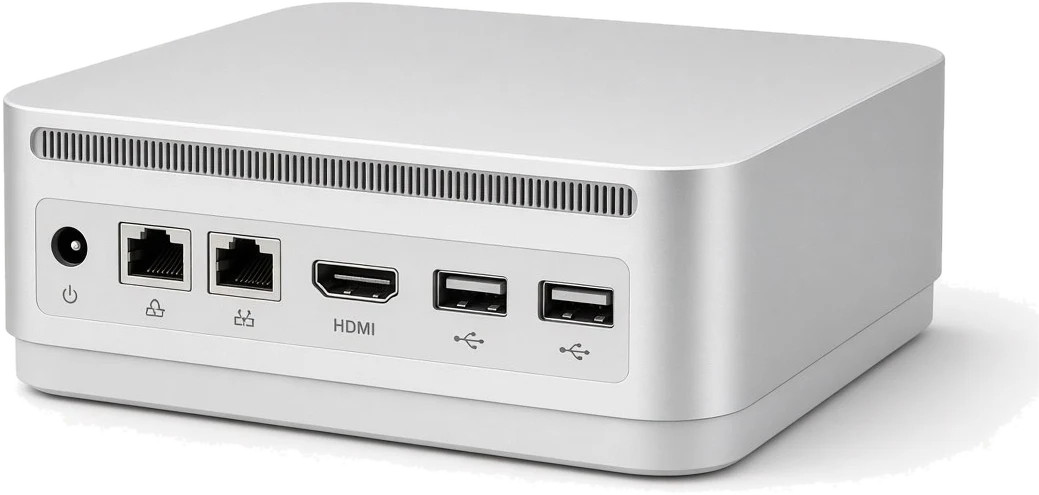
135 × 135 × 63 mm
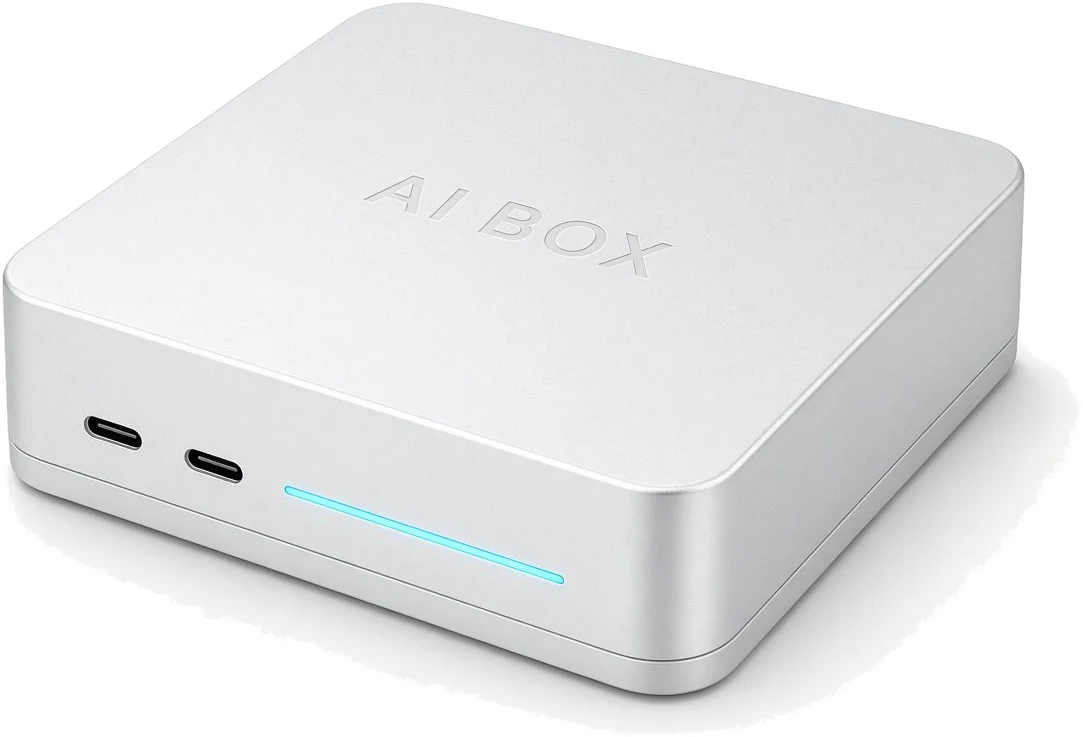
Aluminum alloy chassis, typical power consumption < 95 W (Max). Front panel: 2 × USB 3.2 Type-C and status light; rear: DC power, 2 × RJ45, HDMI, 2 × USB 3.2 Type-A. Wi-Fi 6E, Bluetooth and 5G / 4G are optional expansions.
Technical specifications
| Model | XSCD_NX_PRO (Max) |
|---|---|
| CPU | Arm A720 × 8 + A520 × 4, Armv9 architecture, 12 cores |
| NPU | 45 TOPS @ INT8 |
| GPU | 400 TOPS @ INT8 (Pro Max: 800 TOPS) |
| VRAM | 64 GB |
| Memory | 16 GB LPDDR5x, up to 64 GB |
| Storage | 512 GB NVMe SSD; TF card expansion |
| Network | 2 × RJ45; optional Wi-Fi 6E / Bluetooth; optional 5G / 4G |
| Display | 1 × HDMI 2.0 / 2.1, up to 4K |
| USB | 2 × USB 3.2 Type-C, 2 × USB 3.2 Type-A |
| Video encoding | 16 channels 1080p@30fps, H.264 / H.265 / AVS2 |
| Video decoding | 128 channels 1080p@30fps, H.264 / H.265 / AVS2 |
| Local models | NPU: Qwen3-30B-A3B, Qwen3-VL-30B-A3B; GPU: Qwen3.5-122B-A10B; ASR: FireRedASR2-LLM |
| Software | Debian 12 / Ubuntu 26.04; CUDA ecosystem; PyTorch, TensorFlow, ONNX Runtime; FFmpeg, GStreamer; ROS |
| Power consumption | Typical < 95 W |
| Dimensions | 135 × 135 × 63 mm |
| Operating temperature | 0 to 50 °C (commercial grade) |
Specifications from XSCD_NX_PRO Product spec sheet V1.0 (October 2026), Max configuration; the final mass-production version prevails.
AI BOX selection and testing
Tell us the model size, number of video channels, concurrent tasks and deployment environment; we will recommend a version and provide a test unit.